Fine-tuning overview
Gemma 4 can reason through problems, call tools, and understand images and audio. Fine-tuning allows you to teach it things it did not know before like domain-specific terminology, a new language or corpus, and capabilities outside of it current skillset. These sets of pages will guide you through fine-tuning, from continued pre-Training and supervised fine-Tuning all the way to reinforcement learning and multi-gpu training.
Fine-tuning is not trivial and might get overwhelming quickly. This page helps you find your way, starting with a map of common paths you can take for fine-tuning Gemma 4 based on specific tasks.
Using a coding agent?
Install the gemma-trainer skill so your agent can prepare your data, pick settings for your GPU, and run fine-tuning for you:
1. The four training stages
LLMs are typically trained in stages. In each stage, the model often sees different kind of data and focuses on different tasks:
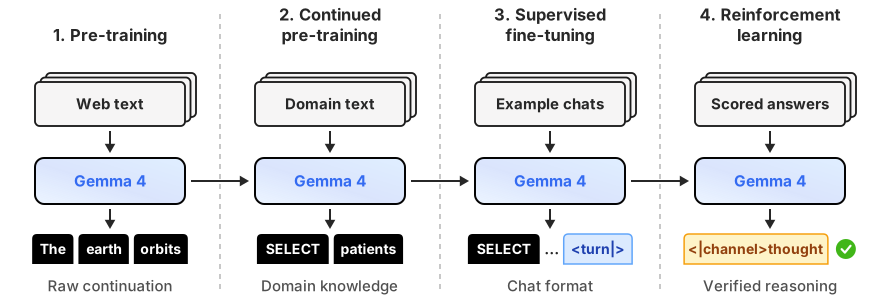
Here is what happens at each stage:
- Pre-training: The model trains on a large corpus of web text, code, images, and audio to predict the next token. The resulting pre-trained checkpoint can continue any document you give it, but it does not follow instructions.
- Continued pre-training: You continue training on raw text from your domain, such as medical literature, a new language, or an internal codebase. The model picks up domain knowledge, terminology, and phrasing. See Continued pre-training.
- Supervised fine-tuning: You train on example conversations, each pairing a prompt with the exact response you want. See (Q)LoRA and Full fine-tuning.
- Reinforcement learning: Instead of imitating a single target answer, the model learns from scored outputs. In preference optimization, it compares chosen and rejected answers. With verifiable rewards, a reward function grades each answer the model generates. See Preference optimization and Verifiable rewards.
You rarely need all four stages. Most teams start from the instruction-tuned (-it) checkpoint, which already follows instructions, and run supervised fine-tuning or reinforcement learning on top.
2. RAG, LoRA, or full fine-tuning
Before you start training, ask yourself whether you actually need to update the weights at all, and if so, whether you need to update all of the model weights.
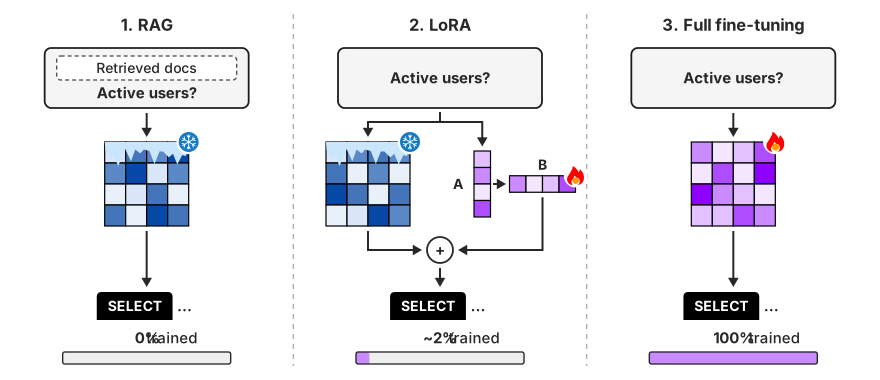
There are generally three approaches to improving your model:
- RAG (Retrieval-Augmented Generation): Leaves the model weights untouched and injects retrieved documents directly into the prompt.
- LoRA (Low-Rank Adaptation): Freezes the base model and trains two small low-rank matrices alongside each layer, updating only about 1% to 2% of the parameters. QLoRA (Quantized Low-Rank Adaptation) uses the exact same adapter technique while storing the frozen base weights in 4-bit precision to save GPU memory.
- Full fine-tuning: Unfreezes and updates 100% of the model weights during backpropagation.
Use this table to match your goal to the right approach:
| Goal | Approach | Reasoning |
|---|---|---|
| Facts that change often, like live inventory or user records | RAG | Updating a search index takes seconds. Weights should learn skills, not changing facts. |
| A new language or a large domain corpus | Continued pre-training | Deep domain shifts benefit from training on raw text before instruction tuning. |
| A new output format, persona, tool schema, or task skill | Supervised fine-tuning | Small adapters learn new behavior from a modest chat dataset on a single GPU. |
| Moving a large model's reasoning into E2B or E4B | Supervised fine-tuning | Train the compact model on reasoning traces generated by 31B. |
| Strict correctness, like verifiable code, math, or SQL | Reinforcement learning | Preference pairs or reward functions catch mistakes that supervised fine-tuning misses. |
Combine RAG and LoRA
RAG and fine-tuning complement each other nicely. A pattern that you see quite often is to fine-tune Gemma 4 using LoRA, so it learns your domain and then you can use RAG to give it more recent information.
3. GPU memory
Training requires significantly more GPU memory than inference. For every parameter you train, the GPU must store three values:
- The weight itself: 2 bytes per parameter in
bfloat16. - Its gradient: How much the weight should change during the backward pass, another 2 bytes.
- Optimizer states: AdamW, and optimizer, tracks two running averages per trained weight. 2 bytes with an 8-bit optimizer, or 8 bytes in 32-bit precision.
On top of those come the activations. These are the intermediate values from the forward pass kept in memory and are used to compute gradients during the backward pass.
Together, they give us the following overview when applied to Gemma 4 12B:
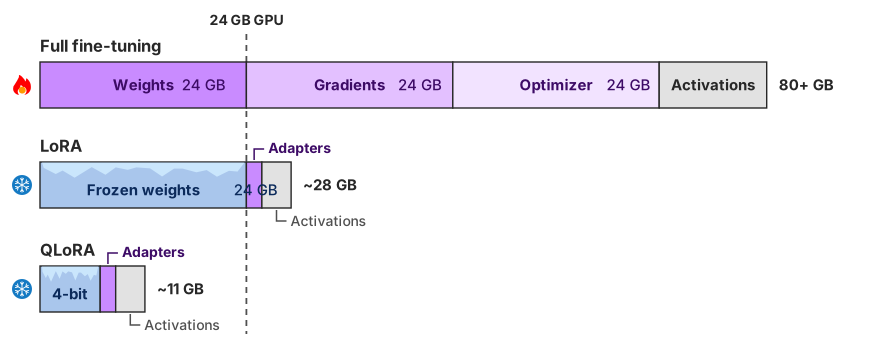
Each method changes how much memory those components use:
As you can see, different training techniques require different amounts of VRAM. The table below shows peak GPU memory (VRAM) across all five Gemma 4 models at a sequence length of 2,048 tokens:
| Model | Parameters | QLoRA | Full fine-tuning |
|---|---|---|---|
| Gemma 4 E2B | 2B effective | ~7 GB | ~32 GB |
| Gemma 4 E4B | 4B effective | ~9 GB | ~42 GB |
| Gemma 4 12B | 12B | ~11 GB | ~80 GB |
| Gemma 4 26B A4B | 26B (4B active) | ~21 GB | ~160 GB |
| Gemma 4 31B | 31B | ~22 GB | ~200 GB |
4. Pre-trained or instruction-tuned
Every Gemma 4 model size is released in two checkpoints:
- Pre-trained (no suffix), such as
google/gemma-4-12B. - Instruction-tuned (
-itsuffix), such asgoogle/gemma-4-12B-it.
A pre-trained model was only trained to continue documents and will generally not respond to instructions. In contrast, an instruction-tuned model will follow instructions, recognizes when to stop, and what the user turns and the model turns are.
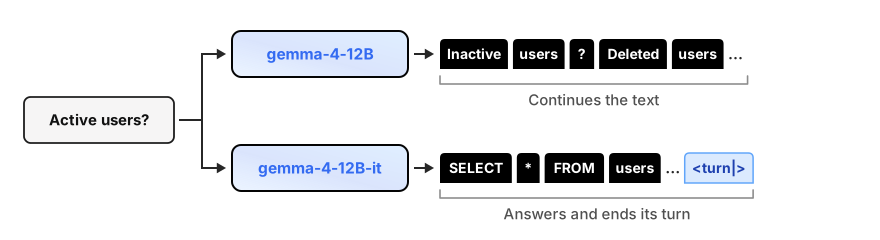
As such, the google/gemma-4-12B-it is a checkpoint that was fine-tuned from the pre-trained google/gemma-4-12B checkpoint. In most cases, users will start from google/gemma-4-12B-it and fine-tune it further.
Use this rule of thumb when picking a checkpoint:
- Start from the
-itcheckpoint for almost everything: Use the-itcheckpoint for supervised fine-tuning, tool use, vision and audio tuning, DPO, and GRPO. You build on top of existing instruction-following behavior instead of teaching it from scratch. - Start from the pre-trained checkpoint for continued pre-training or custom chat formats: Use a pre-trained checkpoint when you want to train on large amounts of data, add a new domain or language, or when you want to add your own chat template. This requires a significant amount of compute as it generally involves a lot of data to perform various stages of full tuning (continued pre-training, supervised fine-tuning, reinforcement learning, etc.).
5. Training frameworks
Gemma 4 works out of the box with various tools frequently used in the ecosystem:
- TRL ↗ SFT, DPO, GRPO, and multi-GPU training in Python.
- Unsloth Swap FastVisionModel into any single-GPU tutorial for faster training and GGUF export.
- Axolotl ↗ YAML-configured fine-tuning for single and multi-GPU runs.
- Vertex AI ↗ Managed fine-tuning jobs on Google Cloud.
- Google Cloud GKE ↗ Multi-GPU fine-tuning on Kubernetes.
What's next
Compare the five Gemma 4 models and pick learning rates and dataset settings.
Format chat turns, mask prompt tokens, and train with thinking tokens.
Run your first fine-tuning job on a single GPU with TRL and PEFT.
Fine-tune the 26B A4B model with Split-LoRA, grouped GEMM, and a frozen router.